Repository navigation
feat(session): 新增 /fast,使用 OpenAI 优先服务档位(Fast 模式) - #1740
Conversation


|
Feasibility check for the implementation as described: |
|
The failing check is the transcript-render probe inside the Trusted extensions Electron E2E job: |

|
Thanks — good catch on the native option. Updated in d4c7795:
On the E2E failure: agreed it's the |

ChatGPT subscribers and OpenAI API users can ask for a faster priority
tier (Responses `service_tier: "priority"`), which costs more plan
limits or a higher per-token price. PI-Desktop never requested a tier.

Model settings now own whether a model may use it: a per-model "Fast
mode" opt-in, enabled for Responses wires, stored in the existing
binding JSON. The cost is a per-conversation choice, so `/fast` toggles
a persisted session switch (schema v25, additive). On a model that is
not configured, `/fast` stores nothing and points to Settings → Models →
Advanced. Launch sends Fast mode only when both are on, and only main
turns carry the field; subagents and compaction keep the default tier.

closes vastsa#1657
pi-ai's Responses and Codex adapters already accept `serviceTier`, send
it as `service_tier`, and price the tier the response reports. Only
`streamSimple` dropped the option while building its base options, which
is why the first version wrote the field through a payload hook.

Forward `serviceTier` in the existing pi-ai patch and pass the native
option on main turns instead. The request bytes are unchanged, and the
Codex adapter can now price a priority request even when the backend
echoes the default tier.
Upstream main took ADR 0331 for plugin session follow and work-panel
reveal while this branch was in review. Renumber the Fast mode record
and its references so the two decisions keep distinct numbers.

d4c7795 to
2289727
Compare
Bring the Fast mode branch up to date with main, which upgraded the Pi
kernel packages from 1.1.0 to 1.3.0 and took ADR numbers 0332 and 0333.

The serviceTier forwarding in buildBaseOptions and SimpleStreamOptions
moves onto the 1.3.0 pi-ai patch, and the lockfile patch hash follows.
Fast mode's ADR is renumbered to 0334; the other conflicts keep both
sides.
Inline visualizations were slow to author. Every model-written fragment
carried its own resize, theme-redraw, axis, and tick-overlap code plus a
pinned D3 tag, and the visualize skill asked the model to read the file
back, which often grew into shell, browser, and screenshot checks.

The visualization shell now preloads the bundled D3 and a small `viz`
helper layer (container sizing and redraw, axes, label overlap, and a
declarative `viz.render` for common charts), and the skill asks for one
write followed by the reply. Fragments written under the earlier skill
keep rendering; their pinned D3 tag is dropped so it cannot replace the
preloaded global.

Measured in the app with deepseek-flash on ten queries, total time went
from 1004.6 s to 498.0 s and model round trips from 95 to 33.
Review of the preload change pointed out that the skill now forbids any
verification, yet one of ten live fragments rendered a blank card
because it targeted a missing container id, and the error only reached
the guest console.

The Write result for a fragment in the session visualization directory
now carries a static check: inline scripts are compiled (never run) and
literal ids passed to viz.render, viz.chart, getElementById, or
querySelector must exist in the fragment. Problems are listed so the
model can fix them with one Edit; a clean write keeps the plain result.
The guest runtime also reports its first uncaught error to the card,
which keeps the frame and shows the message as bounded plain text.
The skill keeps its ban on self-verification, because a live run
without it brought back Bash, browser, and read-back detours (82 vs
30 round trips over ten queries).

The viz helpers also get review fixes: date-only strings parse as
local dates, year-like values skip thousands separators, re-rendering a
container replaces the previous chart, destroy is idempotent, and arc
and heatmap specs report missing channels.
The sidecar reuses a session's runtime and applies the launch-resolved
fastMode with setFastMode, but nothing crossed that seam: the runtime
suite never asserted a request body, and the wire-level test only covered
withFastModeOptions in isolation. A regression in that one call would
silently keep the previous tier for the rest of the session.

Assert that toggling mid-session changes the next request's service_tier
in both directions, and that the switch stays outside the runtime
identity so the reuse path (and its setFastMode call) actually runs.
|
补一个回归测试,覆盖 中途切换走的是「会话 runtime 复用 + 新增
已做变异验证:把 |

Store repeated structured image data and proven JSON mirrors through a reversible binary storage envelope so recovery files keep each image once without changing delivered messages. Reject corrupt references explicitly and require queued session appends to drain before ID-based history mutations.
Keep large retained image histories inside the Host during deletion and
pending-prompt retraction instead of uploading an entire transcript.
Verify durable turn ownership before retracting a stopped prompt and
preserve revision archives and surviving message attribution.

Allow revision activation to require its canonical Host prefix while
retaining the existing explicit-prefix RPC behavior for older callers.
Normal transcript mutations were uploading retained tool images to Host,
which could exceed the fixed request limit. Address durable rows by ID
behind strict outbox drain and rewrite fencing while preserving legacy
replacement and explicit revision-prefix contracts.

Restore stopped drafts only after Host confirms retraction, and preserve
newer prompts, session caches, and late callbacks across awaited results.
Reject restoration failures before runtime admission so corrupt history
cannot silently start a prompt with empty context.
The new local history commands must preserve the same read-only boundary\nas the snapshot operations they replace. Cover keyboard and service calls\nthat bypass disabled remote controls.
Host mutation serialization left renderer history reads free to overlap.
A second delete could reload the pre-delete transcript and resurrect an
already removed turn even when both durable deletions succeeded.

Queue each session's full read, optimistic update, and result settlement
before starting the next delete. Release the queue on every exit and
recheck the active session so failures and session switches cannot hold
or redirect queued work. Deferred regressions cover both first-request
outcomes while retaining unrelated late transcript callbacks.
Protect pending target-session appends before awaiting an active flush so permission, foreign-key, and retry-exhaustion failures cannot masquerade as durable writes. Keep normal flush disposal unchanged and observe startup load rejection immediately while preserving fail-closed errors for later callers.
Nested result mirrors otherwise retain escaped copies of image payloads
inside their enclosing JSON strings. Store proven canonical mirror tokens
as text dependencies while preserving their original source spelling.

Resolve dependencies before restoring business values, rejecting invalid
indices, cycles and references outside proven mirror tokens explicitly.
Screenshot histories duplicate binary strings across structured results
and exact JSON mirrors. Store them once per record and restore complete
business values before consumers see them, including nested mirrors.

Convert legacy files atomically at first write, retain storage markers,
and keep structured paths and proven mirrors consistent during profile
relocation. A backed-up version gate prevents older apps from silently
misreading the new representation.

Exercise real large histories, bounded mutations, restarts and relocation
without raising the transport limit or hiding failed persistence.

Fixes vastsa#1868
A missing durable message is an acknowledged no-op, so it must not
commit the renderer's guessed removal of an entire user turn. Restore
the affected projection and cache while retaining messages and terminal
updates received during the request, including after a session switch.

Verify quarantined recovery entries remain manual-only across restart
and mutation preparation without blocking unrelated history mutations.
Reject malformed encoded records before append or update changes the
transcript or derived index. Cache only decoder-verified file generations
and advance the proof after an owned append is synced and closed.

Keep historical malformed plain rows skippable during legacy conversion,
invalidate proofs on rewrites and deletion, and retain constant-time
normal appends with generation-aware regression coverage.
Prove that existing current-format corruption refuses both append and
update without changing files, and that nested mirror validation agrees
across codecs. Exercise metadata restoration with writable Windows test
handles instead of skipping the identity check.

Keep legacy conversion validation explicit without a new lint warning,
and correct the unrelated schema number changed by the storage bump.
Snapshot rollback can resurrect a provisional native row after a terminal
event gives it a durable ID. Preserve the event-processed projection until
Host confirms deletion, then update its cache and retained panes from the
current messages, including when the runtime LRU entry was evicted.

Cover missing targets, failures, late re-keys, newer turns, session
switches, retained panes, and cache eviction without uploading history.
Chromium background CONNECT requests can reach the test proxy and throw
its localhost assertion outside the async runner, leaving Electron alive
until the deadline. Deny non-fixture destinations with 502 and fail
uncaught fixture assertions immediately instead of hiding the failure.

Inject an unrelated CONNECT request as a deterministic regression while
retaining provider authentication, certificate, redirect, cancellation,
and proxy assertions with the original deadlines.
Upstream took schema v25 for model discovery state, so the session
Fast mode column moves to v26: the v25-to-v26 migration keeps a v25
backup and runs after the model discovery step in both upgrade paths.
Specs and ADR 0334 now cite the renumbered version.

Temporarily hide the composited plugin view while its tab menu is open, then restore it without changing bounds. This prevents Browser chrome from covering renderer menu items.
Use a Main-owned native popup over plugin WebContentsViews instead of hiding the entire Browser surface while a renderer menu is open. Preserve page visibility and validate selected actions against the originating session.

 vastsa
left a comment
vastsa
left a comment
There was a problem hiding this comment.
发现一个需要修复的 Fast 授权边界问题,当前不建议合入。
在 packages/agent-runtime/src/runtime.ts:2860-2878,可信扩展可在 runtime 空闲时通过 bridge 的 setModel 切换当前模型;applyExtensionAgent 会更换 provider/model,但不清除或重新计算 fastMode。随后主回合在 runtime.ts:2242-2253 只按新模型的 API 类型检查,仍会把 serviceTier: "priority" 传给支持 Responses 的扩展模型。
复现路径:用户在已允许 Fast 的普通 Responses 模型上开启会话 Fast;可信扩展随后调用 setModel 切到自己的 Responses 模型;下一条主回合仍会请求 priority。扩展模型没有对应的 fastModeAllowed 用户设置,而启动时的绑定校验只覆盖原普通模型,因此会绕过该模型的显式 opt-in,可能额外消耗订阅额度或产生更高 API 费用。
请在模型切换时清除或按目标模型重新校验 Fast 授权,并加回归测试覆盖“Fast 开启后切到扩展 Responses 模型,请求不带 priority”。修复后请更新到最新 main(当前 PR 还与 main 的中文 E2E 计划有冲突)并重新请求 review。
# Conflicts:
#	docs/project/unreleased.md
#	docs/zh-CN/spec/06-delivery/04-e2e-test-plan.md
Integrate the contributor branch with the current main line so its native tab-menu behavior can be validated against the live work-panel lifecycle.
Native menu positions are renderer CSS pixels, so app zoom must be applied before Main clamps the popup to window DIPs. Resolve pending menu requests when the owning window closes to avoid retaining a dead renderer request.

Exercise request validation, zoom conversion, window-close settlement, and the Browser-active sibling-tab path; document the native styling and IPC contract in both language specs.
The session /fast switch is authorized per stored model binding: Main
only sends it when that binding has fastModeAllowed. A trusted extension
could then move an idle runtime to its own Responses model through the
bridge setModel, and the runtime kept the switch, so the next main turn
asked for the priority tier on a model the user never opted in for.

Clear the switch whenever an extension model is applied. The next launch
re-applies it from the session's stored binding through setFastMode.
…menu-publish

fix(work-panel): keep native tab menus above Browser
# Conflicts:
#	pnpm-lock.yaml
|
感谢指出,已按建议修复(18a040327)。 修复: 回归测试: 文档:ADR 0334 决策 4、 更新 main:已 merge 最新 main(没有 force-push),解决了中文 E2E 计划和 麻烦再帮忙 review 一下。 |
Preserve the current release notes while integrating the inline visualization performance changes.
perf(chat): preload chart helpers for inline visualizations
fix(storage): persist tool images losslessly and bound history mutations
|
@vastsa 已按 review 意见改好:扩展切换模型时会清除 Fast,补了回归测试,也已更新到最新 main,CI 全绿。具体改动见上一条评论,麻烦有空再 review 一下,谢谢! |
Upgrade the pinned Pi release group and migrate its compatibility patches
to preserve the desktop's provider, session, and extension behavior.

Set explicit agent identity so Pi's detailed user agent remains while
its default attribution headers stay disabled, with offline coverage.
Record the candidate base, offline E2E suites, results, and reused test
environment so the compatibility evidence stays tied to the release notes.
chore(deps): sync Pi runtime to 1.4.0

Resolve the conflicts between the Fast mode branch and the current main so
the feature can land as one reviewed candidate.

- Schema: main already shipped v26 (lossless tool-image storage), so the
  session `fast_mode` column becomes v27 with a v26 backup and the post-match
  chain now walks 24 → 25 → 26 → 27.
- pi-ai 1.4.0: the Fast mode patch hunk only existed against 1.3.0. Rebuilt it
  on the 1.4.0 patch by forwarding `serviceTier` in `buildBaseOptions` and
  declaring it on `SimpleStreamOptions`, then refreshed the lockfile patch hash.
- Specs: keep both the hosted-search/identity paragraphs and the Fast mode
  wording; mark v26 as the image-storage step and v27 as the Fast mode step.

|
已把分支更新到最新
本地验证: |


Closes #1657
做了什么
给订阅制 ChatGPT(Codex)和 OpenAI Responses 接口加上 Fast 模式:请求会携带
service_tier: "priority",即 OpenAI 的优先档位。回复更快,但订阅会更快消耗额度,API key 则按更高的 token 单价计费。按照讨论中的建议,能不能开由模型设置决定,开不开由会话决定:
/fast:为当前会话开关 Fast。状态会保存,重启后保留,fork 会复制;在空白首页发送时,记在新任务草稿上,带进创建出的会话。/fast不改任何状态,只提示「该模型未配置 Fast 模式,请到「设置 → 模型 → 高级」中开启」。后续如何使用
/fast:弹出「已为当前会话开启 Fast 模式」,模型标签旁出现 ⚡。/fast即可关闭。其他会话不受影响,新会话默认关闭。截图
隔离 profile 加本地假 Responses 端点(无 API key),端点会把收到的
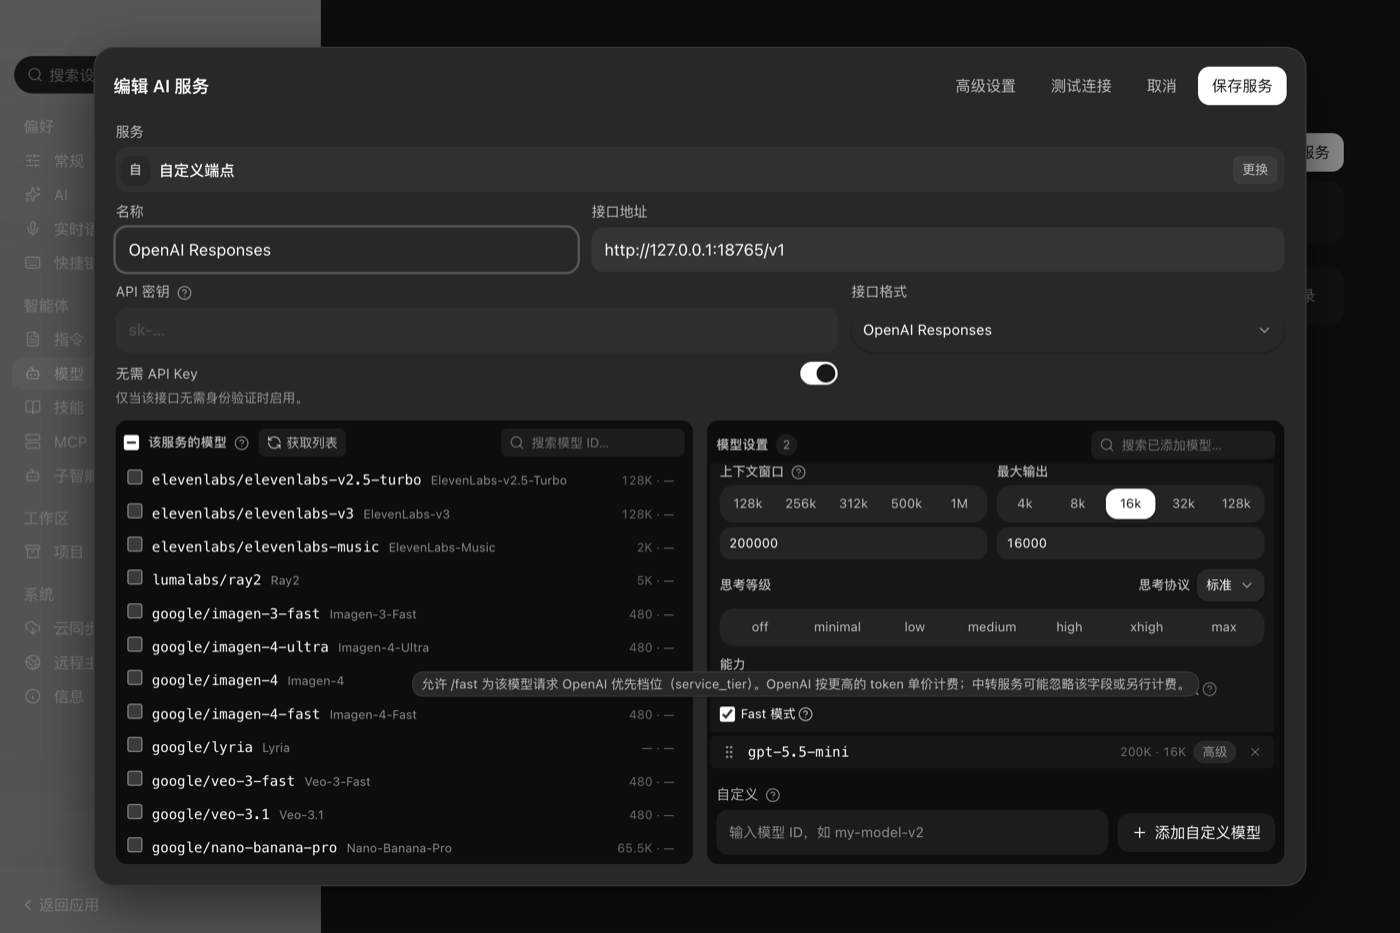
service_tier回显在回复里。1. 设置 → 模型 → 高级 → 能力:Fast 模式(附计费提示)
2.
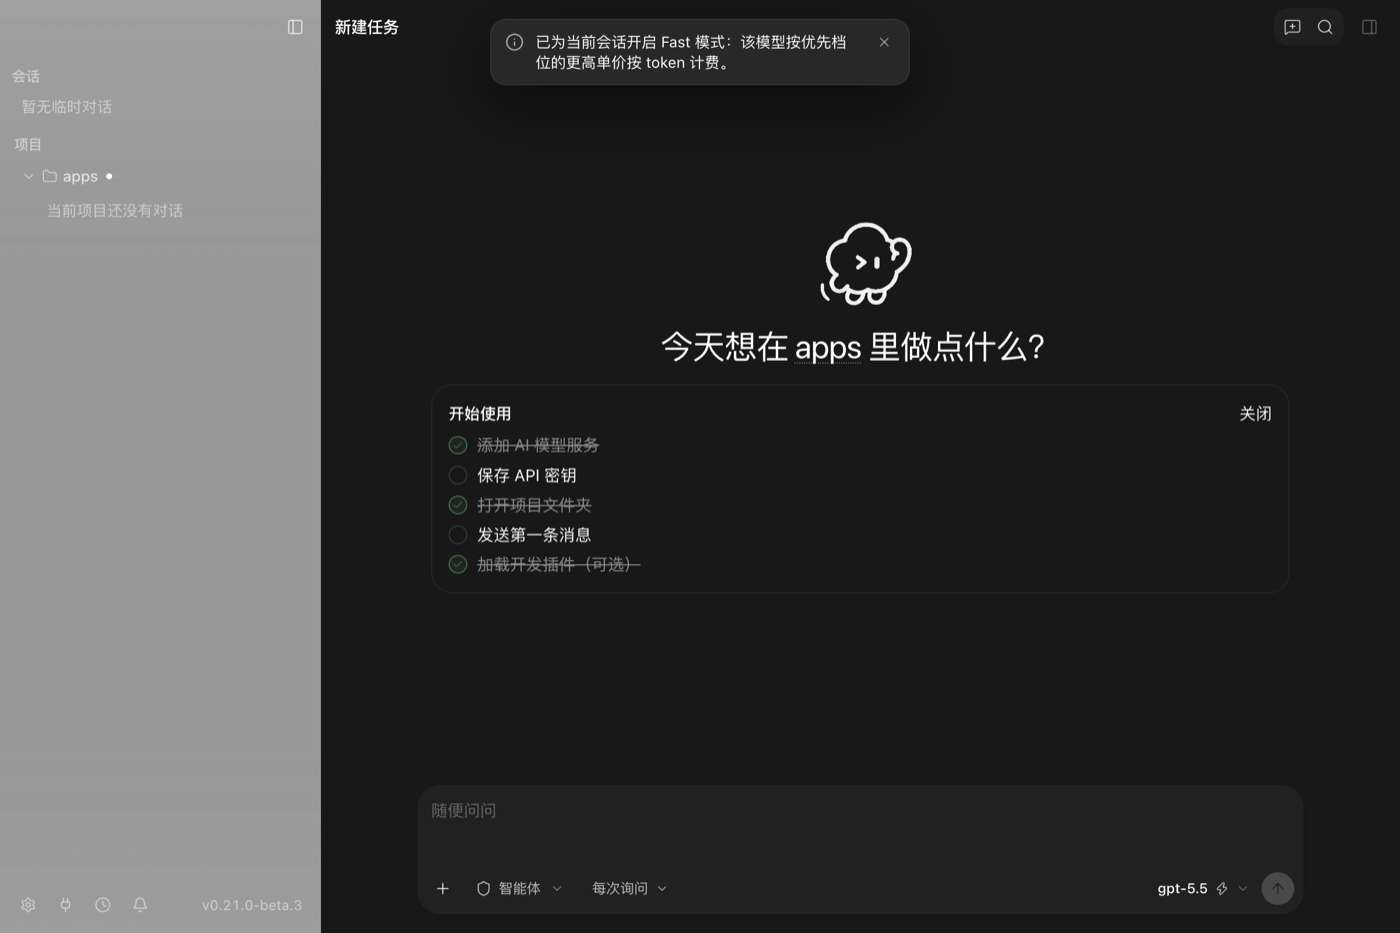
/fast开启:提示 + 模型标签 ⚡3. 发送消息:请求体带
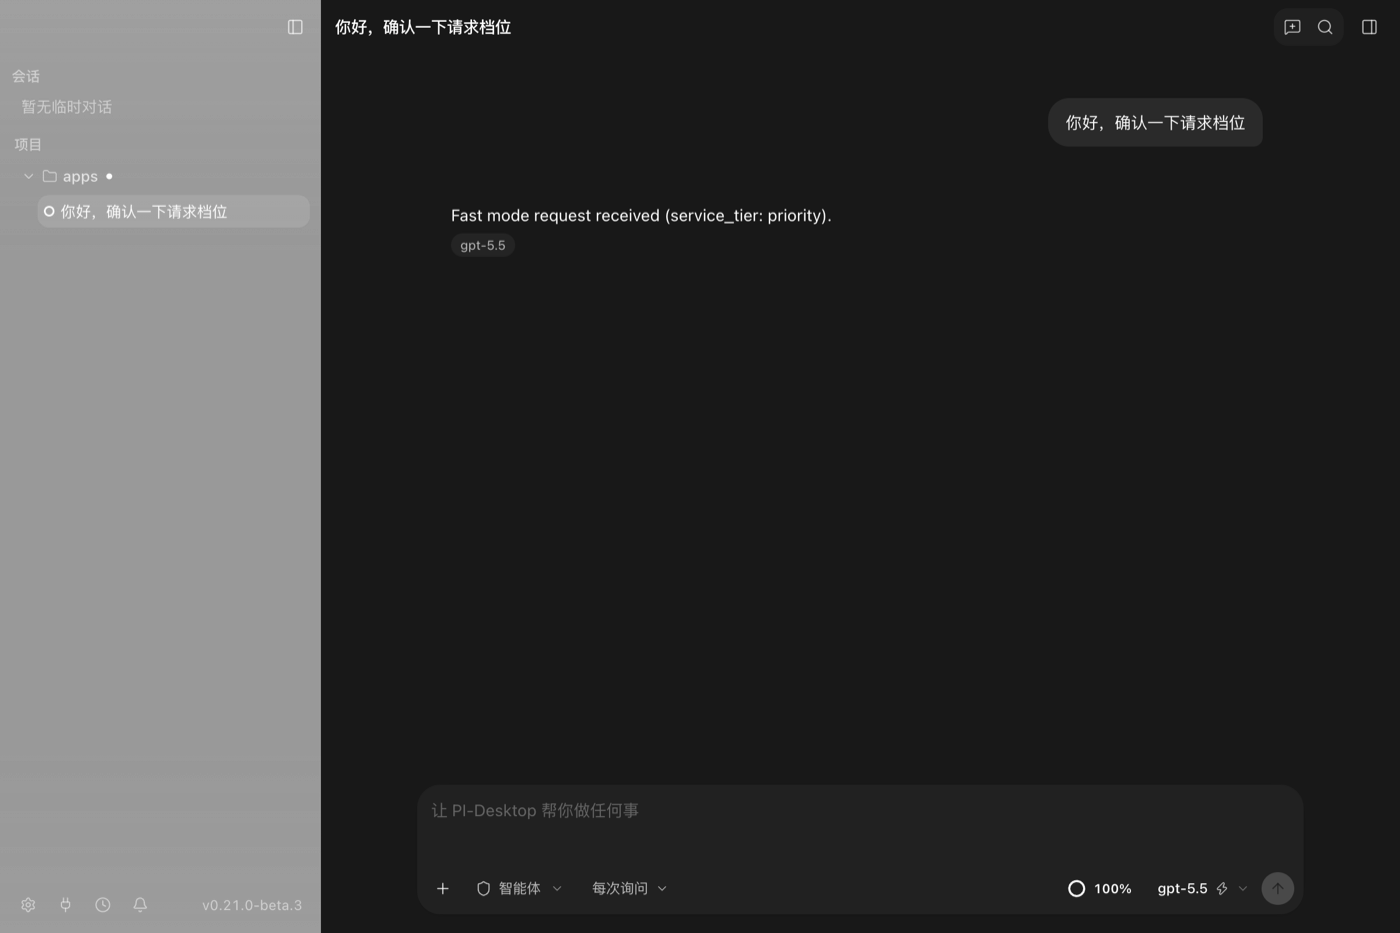
service_tier: priority(端点记录:{"path":"/v1/responses","model":"gpt-5.5","service_tier":"priority"})4. 切到未配置的模型后发送
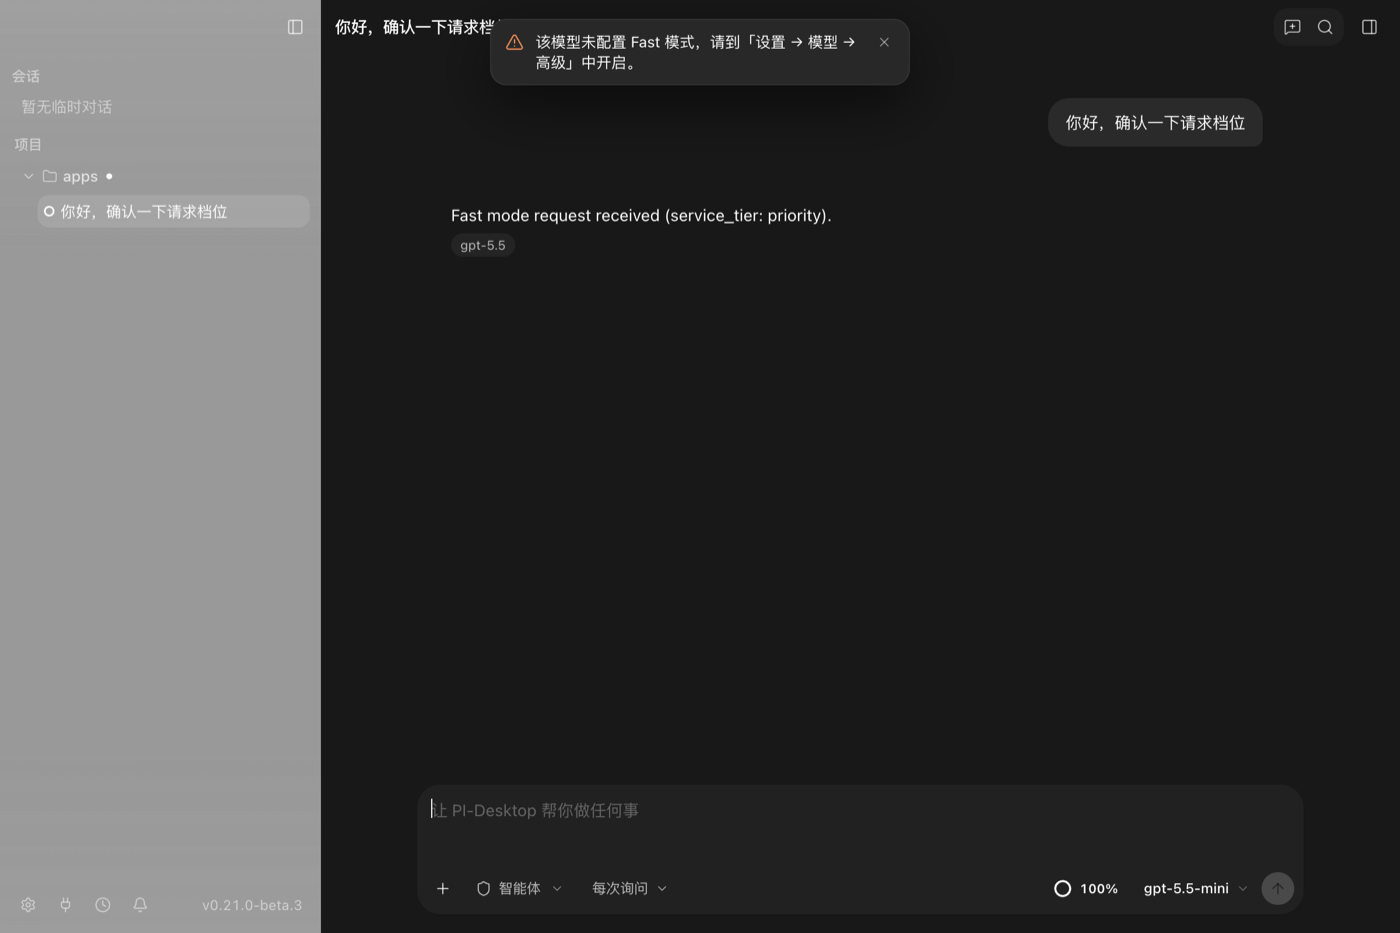
/fast:提示去设置里配置实现
ModelBinding.fastModeAllowed,存在已有的 providerconfig_json里(与nativeWebSearch相同),无需迁移;provider 同步、复制与导入链路都已带上该字段。sessions.fast_mode(schema v25,仅新增一列,迁移前备份 v24)。session.create/session.configure接受可选布尔值fastMode,缺省保留原值,非布尔值返回INVALID_PARAMS。fork 复制该值,定时任务和委托子会话从关闭开始。远程会话拒绝该字段。session-launch只有在「会话开启 + 用户保存的模型绑定允许」时才向 sidecar 传fastMode: true。这里直接读用户保存的绑定,因为 Codex 这类 OAuth 账号的模型配置不经过它。openai-codex-responses/openai-responses时传入 pi-ai 原生的serviceTier: "priority",由适配器写入service_tier并按档位计价。pi-ai 的streamSimple组装参数时会丢掉serviceTier,所以在已有的 pi-ai 补丁里加了一行转发(dist/api/simple-options.js),并在SimpleStreamOptions类型里声明该字段。验证
streamSimple(Responses / Completions)检查请求体;session-launch 判断;/fast用户路径(草稿 → 创建会话、开关、未配置、远程会话、Composer 标识);设置页契约。pnpm lint、desktop typecheck、cargo fmt --check、cargo clippy通过。data_relocation(macOS 本地环境),以及 agent-runtimesubagent-fallback的 429 用例超时(撤掉本改动后在同一 main 上同样失败)。/fast→ 实际请求体。未使用真实 ChatGPT 账号发送请求。风险