Repository navigation
Expand file tree
/
Copy pathscript.py
More file actions
140 lines (109 loc) · 4.79 KB
/
Copy pathscript.py
File metadata and controls
140 lines (109 loc) · 4.79 KB
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
128
129
130
131
132
133
134
135
136
137
138
139
140
import os
import json
from urllib.parse import quote
import re
import stat
import tempfile
from pathlib import Path
HEADER = """# 科幻小说作品集
## 贡献者 Contributors
[](https://github.com/VeejaLiu/ScienceFictionCollection/graphs/contributors)
## 作者
"""
SIZE_UNIT = ["B", "KB", "MB", "GB"]
def get_file_size(file_path):
unit_level = 0
file_size = os.path.getsize(file_path)
for i in range(3):
if file_size > 1000:
unit_level += 1
file_size = file_size / 1000
else:
break
return str(round(file_size, 2)) + SIZE_UNIT[unit_level]
def add_books_from_directory(path, indent_level=0):
"""递归生成目录内容;不跟随符号链接或收录隐藏文件。"""
markdown = ""
indent = " " * 2 * indent_level # 生成缩进
directories = []
files = []
for entry in os.scandir(path):
if entry.name.startswith('.') or entry.is_symlink():
continue
if entry.is_dir():
directories.append(entry.name)
elif entry.is_file():
files.append(entry.name)
# 先写目录,再写文件
for directory in sorted(directories):
markdown += f"{indent}- {directory}\n"
markdown += add_books_from_directory(os.path.join(path, directory), indent_level + 1)
for file in sorted(files):
book_size = get_file_size(os.path.join(path, file))
missing_note = " **(空文件,正文缺失)**" if os.path.getsize(os.path.join(path, file)) == 0 else ""
markdown += f"{indent}- {file} _[{book_size}]_{missing_note}\n"
return markdown
def author_directories(root):
return sorted(path.name for path in root.iterdir()
if path.is_dir() and not path.is_symlink()
and re.match(r'^\d{3} - .+', path.name))
def generate_readme(root):
metadata_file = root / 'metadata' / 'authors.json'
records = json.loads(metadata_file.read_text(encoding='utf-8'))['authors'] if metadata_file.exists() else []
by_directory = {author['directory']: author for author in records}
markdown = HEADER
for directory in author_directories(root):
author = by_directory.get(directory)
name = author['name'] if author else directory
english = author.get('names', {}).get('en') if author else None
if english and english != name:
name += f' · {english}'
markdown += f"- [{name}]({quote(directory, safe='')}/)\n"
markdown += '\n## 作品\n\n' + generate_work_list(root)
return markdown + """
## 更多
[在线阅读](https://veejaliu.github.io/ScienceFictionCollection-Web/) · [项目说明](docs/PROJECT.md) · [授权范围](LICENSE-SCOPE.md) · [Web 仓库](https://github.com/VeejaLiu/ScienceFictionCollection-Web)
## Star History
[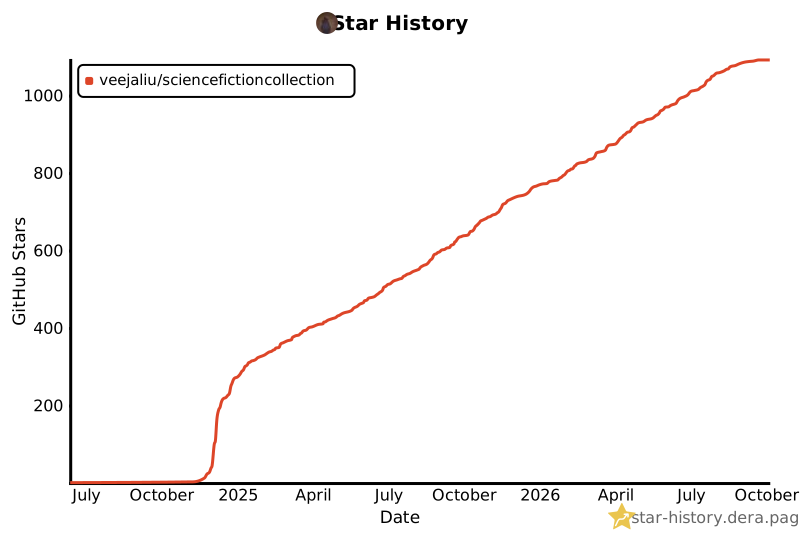](https://star-history.dera.page/#VeejaLiu/ScienceFictionCollection&Date)
"""
def generate_catalog(root):
authors = author_directories(root)
markdown = '# 完整作品目录\n\n[返回仓库首页](README.md) · [在线阅读](https://veejaliu.github.io/ScienceFictionCollection-Web/)\n\n由 `script.py` 根据目录和文件大小生成,不读取小说正文。\n\n## 作者索引\n\n'
for author in authors:
anchor = re.sub(r'[^\w\s-]', '', author.lower()).strip()
anchor = re.sub(r'\s+', '-', anchor)
markdown += f"- [{author}](#{anchor})\n"
return markdown + '\n## 作品\n\n' + generate_work_list(root)
def generate_work_list(root):
markdown = ''
for author in author_directories(root):
markdown += f"### {author.rstrip()}\n"
markdown += add_books_from_directory(root / author)
return markdown
def write_document(target, text):
content = text.encode('utf-8')
if target.exists() and target.read_bytes() == content:
print(f'{target.name} 已是最新。')
return
mode = stat.S_IMODE(target.stat().st_mode) if target.exists() else 0o644
with tempfile.NamedTemporaryFile(dir=target.parent, prefix='.readme-', delete=False) as file:
temporary = Path(file.name)
try:
file.write(content)
file.flush()
os.fsync(file.fileno())
os.fchmod(file.fileno(), mode)
except BaseException:
temporary.unlink(missing_ok=True)
raise
try:
os.replace(temporary, target)
finally:
temporary.unlink(missing_ok=True)
print(f'{target.name} 已更新。')
def main():
root = Path(__file__).resolve().parent
write_document(root / 'README.md', generate_readme(root))
write_document(root / 'CATALOG.md', generate_catalog(root))
if __name__ == '__main__':
main()