diff --git a/.github/workflows/ci.yml b/.github/workflows/ci.yml
index fcb2008..cdae7e1 100644
--- a/.github/workflows/ci.yml
+++ b/.github/workflows/ci.yml
@@ -23,6 +23,22 @@ jobs:
- name: Type-check
run: uv run --frozen mypy
+ reproduce:
+ # Every committed benchmark table, summary and figure, regenerated offline and compared with the repository.
+ timeout-minutes: 20
+ runs-on: ubuntu-latest
+ steps:
+ - uses: actions/checkout@v4
+ - uses: actions/setup-python@v5
+ with:
+ python-version: '3.12'
+ - name: Install locked tooling
+ run: python -m pip install uv==0.12.17
+ - name: Install locked project
+ run: uv sync --frozen --extra dev
+ - name: Reproduce every result and figure
+ run: uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py
+
verify:
timeout-minutes: 15
strategy:
diff --git a/CHANGELOG.md b/CHANGELOG.md
index 8f3b337..ac10990 100644
--- a/CHANGELOG.md
+++ b/CHANGELOG.md
@@ -2,6 +2,12 @@
## Unreleased
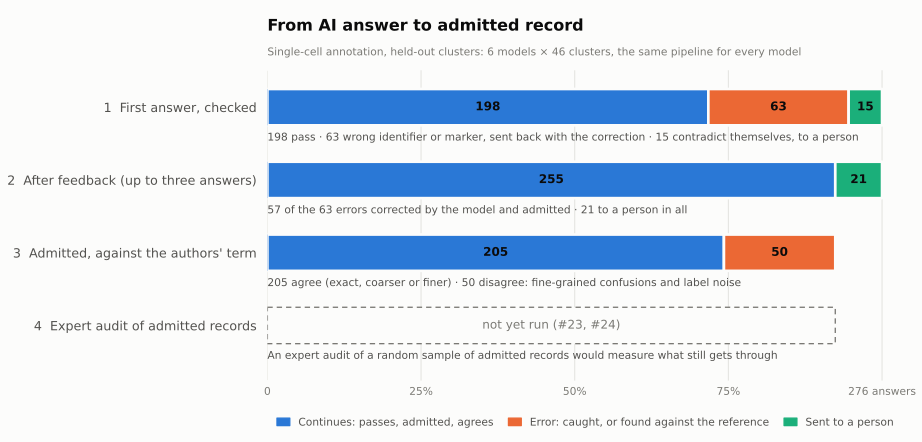
+- Add `tools/reproduce.py`: one command regenerates every committed benchmark table, summary and figure
+ offline (18 steps, about three minutes) and compares each with the repository; CI runs it on every
+ change. It caught the ClinVar and VBO figures still captioned v0.7.0 after the release, now fixed.
+- Add the funnel figure (`docs/assets/ai_validation_funnel.svg`): single-cell held-out answers, stage
+ by stage, from the first check through feedback to what was admitted and how it compares with the
+ authors' terms. Cell-type summaries now record these stages.
## 0.8.0 — AI validation: grounding, generic grounders, the feedback loop and benchmarks
Bioevidence now checks AI output against pinned sources and reference releases, feeds fixable
diff --git a/README.md b/README.md
index 5716107..9258e3c 100644
--- a/README.md
+++ b/README.md
@@ -95,6 +95,10 @@ The same loop corrects identifiers in single-cell annotation. Claude Haiku 4.5 l
Its second answer, `CL:0000173`, was admitted and is exactly the authors' annotation.
+Across all 276 held-out annotations, stage by stage:
+
+
+
**Failure handling**, each in the code and exercised in the runs:
| Failure | Detected by | Handling |
@@ -240,6 +244,24 @@ More: [draft format](https://github.com/NingyuSUN/bioai-evidence-validator/blob/
+## Reproduce every number
+
+```bash
+uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py
+```
+
+One command regenerates every committed benchmark table, summary and figure, offline, in about three minutes,
+and compares each with the repository byte for byte (text files with line endings normalised). It runs 18 steps,
+also run in CI on every change:
+- the three real-data cases;
+- ten LLM-benchmark result sets;
+- the task files and the error taxonomy;
+- the figures.
+
+Model calls, agent runs and downloads are not repeated. What they produced is committed and pinned by
+SHA-256: model answers, agent episodes, the verification of cited papers, and source snapshots. `--write` updates the
+committed files and `--list` shows the steps.
+
## Limits
- **Admission is not truth.** It means the record meets the selected profile: its evidence exists in the
@@ -256,8 +278,8 @@ More: [draft format](https://github.com/NingyuSUN/bioai-evidence-validator/blob/
Tracked in the [AI validation roadmap](https://github.com/NingyuSUN/bioai-evidence-validator/blob/main/docs/AI_VALIDATION_ROADMAP.md) (#26):
- expert review of the benchmark cases (#23);
- calibrated triage and audit sampling of admitted records, to measure what still gets through (#24);
-- one-command reproduction of every benchmark, a funnel figure, and a validation dossier for release
- 0.8.0 (#25).
+- a validation dossier structured like FDA's draft AI credibility framework (#25). One-command reproduction
+ and the funnel figure are done.
## Contributing and citing
diff --git a/docs/ENGINEERING.md b/docs/ENGINEERING.md
index d1d2769..119e3e9 100644
--- a/docs/ENGINEERING.md
+++ b/docs/ENGINEERING.md
@@ -297,8 +297,18 @@ uv sync --frozen --extra dev
uv run --frozen pytest
uv build
uv run --isolated --no-project --with ./dist/*.whl python tools/check_distribution.py
+uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py # every benchmark result and figure
```
+`tools/reproduce.py` regenerates every committed benchmark table, summary and figure offline from what is
+committed, and compares each with the repository: text with line endings normalised, everything else byte for
+byte. What it replays from:
+- for the real-data cases, the hash-checked source snapshots;
+- for the LLM benchmark, the recorded model answers, agent episodes and paper verifications;
+- for the figures, the summaries, with matplotlib pinned.
+
+CI runs it on every change, and a test fails if a results directory or figure is not covered by one of its steps.
+
CI runs on Linux/Python 3.11–3.14 and Windows/Python 3.13, and runs the GitHub Action on
Linux and Windows. Tests cover multi-domain acceptance, negative evidence cases,
use-specific human review, strict configuration/JSON/draft parsing, baseline enforcement,
diff --git a/docs/assets/ai_validation_funnel.svg b/docs/assets/ai_validation_funnel.svg
new file mode 100644
index 0000000..f106479
--- /dev/null
+++ b/docs/assets/ai_validation_funnel.svg
@@ -0,0 +1,2706 @@
+
+
+
diff --git a/docs/assets/clinvar_germline_benchmark.svg b/docs/assets/clinvar_germline_benchmark.svg
index 5f83425..75641b7 100644
--- a/docs/assets/clinvar_germline_benchmark.svg
+++ b/docs/assets/clinvar_germline_benchmark.svg
@@ -4040,7 +4040,7 @@ z
-
+
-
+
diff --git a/docs/assets/vbo_canine_benchmark.svg b/docs/assets/vbo_canine_benchmark.svg
index eb6381e..8ac34ef 100644
--- a/docs/assets/vbo_canine_benchmark.svg
+++ b/docs/assets/vbo_canine_benchmark.svg
@@ -2985,7 +2985,7 @@ z
-
+
-
+
diff --git a/docs/index.md b/docs/index.md
index dde5574..d9b96b7 100644
--- a/docs/index.md
+++ b/docs/index.md
@@ -91,6 +91,10 @@ The same loop corrects identifiers in single-cell annotation. Claude Haiku 4.5 l
Its second answer, `CL:0000173`, was admitted and is exactly the authors' annotation.
+Across all 276 held-out annotations, stage by stage:
+
+
+
**Failure handling**, each in the code and exercised in the runs:
| Failure | Detected by | Handling |
diff --git a/evaluation/llm_benchmark/celltype_loop.py b/evaluation/llm_benchmark/celltype_loop.py
index bfdd0a2..c33b8e0 100644
--- a/evaluation/llm_benchmark/celltype_loop.py
+++ b/evaluation/llm_benchmark/celltype_loop.py
@@ -379,6 +379,7 @@ def metrics(mine: list[dict], name: str) -> dict:
if r["attempts"] and "BEV026" in r["attempts"][0]["codes"]:
flagged[outcome(case, truth[r["task_id"]]["term"], got[0])] += 1
summary["definition_flags_on_first_answers"] = dict(sorted(flagged.items()))
+ summary["funnel"] = funnel(case, truth, rows)
(results / "summary.json").write_text(json.dumps(summary, indent=2, sort_keys=True) + "\n", encoding="utf-8",
newline="\n")
(results / "summary.md").write_text(render(summary), encoding="utf-8", newline="\n")
@@ -386,6 +387,44 @@ def metrics(mine: list[dict], name: str) -> dict:
return summary
+def first_answer_stage(attempt: dict) -> str:
+ """What the checks found in an episode's first record, most decisive first."""
+ if attempt["status"] == "admitted":
+ return "passed"
+ fixable = [f for f in attempt["findings"] if f["rule_id"] not in feedback.EXPERT]
+ if any(f["rule_id"] in ("BEV017", "BEV023", "BEV024") or (f["rule_id"] == "BEV016" and f["where"].startswith("object"))
+ for f in fixable):
+ return "identifier error"
+ if any(f["rule_id"] == "BEV016" for f in fixable):
+ return "marker not in the data"
+ if any(f["rule_id"] == "BEV026" for f in fixable):
+ return "definition contradicted"
+ return "conflict, to a person" if attempt["to_expert"] else "other finding"
+
+
+def funnel(case: Case, truth: dict, rows: list[dict]) -> dict:
+ """Stage by stage: the first answer's checks, what feedback did with the fixable ones, and how the admitted
+ annotations compare with the authors' terms. The expert audit of admitted records is not yet run (#24)."""
+ first, final, fixed, reference = (collections.Counter() for _ in range(4))
+ for r in rows:
+ if not r["attempts"]:
+ first["no annotation"] += 1
+ final["no annotation"] += 1
+ continue
+ stage = first_answer_stage(r["attempts"][0])
+ first[stage] += 1
+ last = r["attempts"][-1]
+ final["admitted" if last["status"] == "admitted" else "to a person"] += 1
+ if stage not in ("passed", "conflict, to a person"):
+ fixed["admitted" if last["status"] == "admitted" else "to a person"] += 1
+ if last["status"] == "admitted":
+ got = [c["answer"] for c in r["calls"] if c["answer"] and c["answer"]["decision"] == "annotate"]
+ kind = outcome(case, truth[r["task_id"]]["term"], got[len(r["attempts"]) - 1])
+ reference["compatible" if kind in ("exact", "coarser", "finer") else "disagrees"] += 1
+ return {"first_answer": dict(sorted(first.items())), "fixable_after_feedback": dict(sorted(fixed.items())),
+ "final": dict(sorted(final.items())), "admitted_against_reference": dict(sorted(reference.items()))}
+
+
def render(summary: dict) -> str:
f = score_claims.fraction
protocol = int(summary["benchmark"].rsplit("v", 1)[1])
@@ -413,6 +452,15 @@ def render(summary: dict) -> str:
if "definition_flags_on_first_answers" in summary:
lines[-1:] = ["", "First answers the definition check flagged, by comparison with the authors' term: "
+ ", ".join(f"{k} {n}" for k, n in summary["definition_flags_on_first_answers"].items()) + ".", ""]
+ if "funnel" in summary:
+ stages = summary["funnel"]
+
+ def listed(counts: dict) -> str:
+ return ", ".join(f"{k} {n}" for k, n in counts.items())
+ lines[-1:] = ["", f"Funnel. First answers: {listed(stages['first_answer'])}. Answers with a fixable finding, after "
+ f"feedback: {listed(stages['fixable_after_feedback'])}. Final: {listed(stages['final'])}. Admitted, "
+ f"against the authors' term: {listed(stages['admitted_against_reference'])}. Expert audit of "
+ "admitted records: not yet run.", ""]
return "\n".join(lines)
diff --git a/evaluation/llm_benchmark/plot.py b/evaluation/llm_benchmark/plot.py
index 2de1625..0ee7cdd 100644
--- a/evaluation/llm_benchmark/plot.py
+++ b/evaluation/llm_benchmark/plot.py
@@ -2,8 +2,8 @@
uv run --with matplotlib python evaluation/llm_benchmark/plot.py
-Reads results/*/summary.json and writes docs/assets/ai_validation_results.svg. Output is deterministic for a given
-matplotlib version (fixed SVG ids, no timestamp).
+Reads results/*/summary.json and writes docs/assets/ai_validation_results.svg and ai_validation_funnel.svg. Output
+is deterministic for a given matplotlib version (fixed SVG ids, no timestamp); reproduce.py pins it.
"""
from __future__ import annotations
@@ -103,9 +103,65 @@ def style(ax) -> None:
spine.set_visible(False)
+def funnel_figure(output: Path) -> None:
+ """Stage by stage, from the models' first answers to admitted records, for the single-cell held-out split."""
+ stages = load("celltype-test")["funnel"]
+ first, fixed, final, ref = (stages[k] for k in ("first_answer", "fixable_after_feedback", "final",
+ "admitted_against_reference"))
+ errors = sum(n for k, n in first.items() if k not in ("passed", "conflict, to a person", "no annotation"))
+ conflicts = first.get("conflict, to a person", 0)
+ rows = [
+ ("1 First answer, checked", [(first["passed"], GOOD), (errors, BAD), (conflicts, PERSON)],
+ f"{first['passed']} pass · {errors} wrong identifier or marker, sent back with the correction · "
+ f"{conflicts} contradict themselves, to a person"),
+ ("2 After feedback (up to three answers)", [(final["admitted"], GOOD), (final["to a person"], PERSON)],
+ f"{fixed.get('admitted', 0)} of the {errors} errors corrected by the model and admitted · "
+ f"{final['to a person']} to a person in all"),
+ ("3 Admitted, against the authors' term", [(ref["compatible"], GOOD), (ref["disagrees"], BAD)],
+ f"{ref['compatible']} agree (exact, coarser or finer) · {ref['disagrees']} disagree: fine-grained confusions "
+ "and label noise"),
+ ]
+ total = sum(first.values())
+ plt.rcParams.update({"svg.hashsalt": "bioevidence-funnel", "font.family": "DejaVu Sans"})
+ fig, ax = plt.subplots(figsize=(9.6, 4.6))
+ fig.patch.set_facecolor(SURFACE)
+ for y, (_, parts, note) in enumerate(rows):
+ left = 0
+ for value, color in parts:
+ if value:
+ ax.barh(y, value, left=left, height=0.5, color=color, edgecolor=SURFACE, linewidth=2)
+ ax.text(left + value / 2, y, str(value), ha="center", va="center", fontsize=9, color=INK,
+ fontweight="bold")
+ left += value
+ ax.text(0, y + 0.42, note, va="center", fontsize=8, color=TEXT)
+ audit = len(rows)
+ ax.barh(audit, final["admitted"], height=0.5, color=SURFACE, edgecolor=MUTED, linewidth=1, linestyle=(0, (4, 3)))
+ ax.text(final["admitted"] / 2, audit, "not yet run (#23, #24)", ha="center", va="center", fontsize=9, color=MUTED)
+ ax.text(0, audit + 0.42, "An expert audit of a random sample of admitted records would measure what still gets "
+ "through", va="center", fontsize=8, color=TEXT)
+ ax.set_yticks(range(len(rows) + 1), [label for label, _, _ in rows] + ["4 Expert audit of admitted records"])
+ ax.set_ylim(audit + 0.75, -0.5)
+ ax.set_xlim(0, total * 1.02)
+ ax.set_xticks([0, total / 4, total / 2, 3 * total / 4, total], ["0", "25%", "50%", "75%", f"{total} answers"])
+ style(ax)
+ ax.text(0, 1.13, "From AI answer to admitted record", transform=ax.transAxes, fontsize=12, fontweight="bold",
+ color=INK)
+ ax.text(0, 1.05, "Single-cell annotation, held-out clusters: 6 models × 46 clusters, the same pipeline for every "
+ "model", transform=ax.transAxes, fontsize=8, color=MUTED)
+ ax.legend(handles=[Patch(color=GOOD, label="Continues: passes, admitted, agrees"),
+ Patch(color=BAD, label="Error: caught, or found against the reference"),
+ Patch(color=PERSON, label="Sent to a person")],
+ loc="upper left", bbox_to_anchor=(0, -0.09), ncol=3, frameon=False, fontsize=8, labelcolor=TEXT,
+ handlelength=1.2, columnspacing=1.4)
+ fig.subplots_adjust(left=0.29, right=0.97, top=0.84, bottom=0.14)
+ fig.savefig(output, format="svg", facecolor=SURFACE, metadata={"Date": None})
+ plt.close(fig)
+
+
def main(argv: list[str] | None = None) -> int:
parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument("--output", type=Path, default=REPO / "docs" / "assets" / "ai_validation_results.svg")
+ parser.add_argument("--funnel", type=Path, default=REPO / "docs" / "assets" / "ai_validation_funnel.svg")
args = parser.parse_args(argv)
plt.rcParams.update({"svg.hashsalt": "bioevidence", "font.family": "DejaVu Sans"})
fig, (top, bottom) = plt.subplots(2, 1, figsize=(9.6, 6.6), gridspec_kw={"hspace": 1.05})
@@ -114,7 +170,9 @@ def main(argv: list[str] | None = None) -> int:
error_panel(bottom)
fig.subplots_adjust(left=0.27, right=0.82, top=0.88, bottom=0.07)
fig.savefig(args.output, format="svg", facecolor=SURFACE, metadata={"Date": None})
- print(f"wrote {args.output}")
+ plt.close(fig)
+ funnel_figure(args.funnel)
+ print(f"wrote {args.output} and {args.funnel}")
return 0
diff --git a/evaluation/llm_benchmark/results/celltype-external/summary.json b/evaluation/llm_benchmark/results/celltype-external/summary.json
index 4a9eb61..1caced6 100644
--- a/evaluation/llm_benchmark/results/celltype-external/summary.json
+++ b/evaluation/llm_benchmark/results/celltype-external/summary.json
@@ -16,6 +16,28 @@
"episodes": 486,
"episodes_sha256": "5448d9f04936064a7df715ac9e48e59e630f30c8bb539a81555fb11e4769a705",
"failed_calls": 0,
+ "funnel": {
+ "admitted_against_reference": {
+ "compatible": 242,
+ "disagrees": 148
+ },
+ "final": {
+ "admitted": 390,
+ "no annotation": 7,
+ "to a person": 89
+ },
+ "first_answer": {
+ "conflict, to a person": 36,
+ "definition contradicted": 71,
+ "identifier error": 70,
+ "no annotation": 7,
+ "passed": 302
+ },
+ "fixable_after_feedback": {
+ "admitted": 88,
+ "to a person": 53
+ }
+ },
"pooled": {
"gate": {
"answered": {
diff --git a/evaluation/llm_benchmark/results/celltype-external/summary.md b/evaluation/llm_benchmark/results/celltype-external/summary.md
index 4e017b7..447c6d5 100644
--- a/evaluation/llm_benchmark/results/celltype-external/summary.md
+++ b/evaluation/llm_benchmark/results/celltype-external/summary.md
@@ -38,3 +38,5 @@ Errors in the models' first answers (all models): label mismatch 69/479, marker
486 episodes, 673 model calls (0 failed), 131 revised after feedback. Rule codes raised across all records: BEV004 69, BEV016 7, BEV017 95, BEV023 1, BEV026 140.
First answers the definition check flagged, by comparison with the authors' term: exact 43, finer 4, wrong 41.
+
+Funnel. First answers: conflict, to a person 36, definition contradicted 71, identifier error 70, no annotation 7, passed 302. Answers with a fixable finding, after feedback: admitted 88, to a person 53. Final: admitted 390, no annotation 7, to a person 89. Admitted, against the authors' term: compatible 242, disagrees 148. Expert audit of admitted records: not yet run.
diff --git a/evaluation/llm_benchmark/results/celltype-pilot/summary.json b/evaluation/llm_benchmark/results/celltype-pilot/summary.json
index f6ef287..5d8a437 100644
--- a/evaluation/llm_benchmark/results/celltype-pilot/summary.json
+++ b/evaluation/llm_benchmark/results/celltype-pilot/summary.json
@@ -11,6 +11,27 @@
"episodes": 144,
"episodes_sha256": "77da377f90c89b884de1918a12e44502ba56ebd4126e751dec889803e5d5c960",
"failed_calls": 0,
+ "funnel": {
+ "admitted_against_reference": {
+ "compatible": 52,
+ "disagrees": 15
+ },
+ "final": {
+ "admitted": 67,
+ "no annotation": 6,
+ "to a person": 71
+ },
+ "first_answer": {
+ "conflict, to a person": 44,
+ "identifier error": 38,
+ "no annotation": 6,
+ "passed": 56
+ },
+ "fixable_after_feedback": {
+ "admitted": 11,
+ "to a person": 27
+ }
+ },
"pooled": {
"gate": {
"answered": {
diff --git a/evaluation/llm_benchmark/results/celltype-pilot/summary.md b/evaluation/llm_benchmark/results/celltype-pilot/summary.md
index 51f13c7..b2cb91e 100644
--- a/evaluation/llm_benchmark/results/celltype-pilot/summary.md
+++ b/evaluation/llm_benchmark/results/celltype-pilot/summary.md
@@ -29,3 +29,5 @@ Each model annotates one cluster from its top 20 marker genes with a Cell Ontolo
Errors in the models' first answers (all models): label mismatch 35/138, marker not in data 3/138, no markers 0/138, not a cell type 0/138, obsolete id 2/138, unapproved symbol 0/138, unknown id 1/138.
144 episodes, 185 model calls (0 failed), 38 revised after feedback. Rule codes raised across all records: BEV004 87, BEV016 4, BEV017 39, BEV023 2, BEV025 29.
+
+Funnel. First answers: conflict, to a person 44, identifier error 38, no annotation 6, passed 56. Answers with a fixable finding, after feedback: admitted 11, to a person 27. Final: admitted 67, no annotation 6, to a person 71. Admitted, against the authors' term: compatible 52, disagrees 15. Expert audit of admitted records: not yet run.
diff --git a/evaluation/llm_benchmark/results/celltype-test/summary.json b/evaluation/llm_benchmark/results/celltype-test/summary.json
index e595926..e6751dc 100644
--- a/evaluation/llm_benchmark/results/celltype-test/summary.json
+++ b/evaluation/llm_benchmark/results/celltype-test/summary.json
@@ -10,6 +10,26 @@
"episodes": 276,
"episodes_sha256": "1826196d4e1b645b90612b674708c850332ca35f38e141fe47e253cdd10b3fa0",
"failed_calls": 0,
+ "funnel": {
+ "admitted_against_reference": {
+ "compatible": 205,
+ "disagrees": 50
+ },
+ "final": {
+ "admitted": 255,
+ "to a person": 21
+ },
+ "first_answer": {
+ "conflict, to a person": 15,
+ "identifier error": 62,
+ "marker not in the data": 1,
+ "passed": 198
+ },
+ "fixable_after_feedback": {
+ "admitted": 57,
+ "to a person": 6
+ }
+ },
"pooled": {
"gate": {
"answered": {
diff --git a/evaluation/llm_benchmark/results/celltype-test/summary.md b/evaluation/llm_benchmark/results/celltype-test/summary.md
index 3f90cda..d583ca1 100644
--- a/evaluation/llm_benchmark/results/celltype-test/summary.md
+++ b/evaluation/llm_benchmark/results/celltype-test/summary.md
@@ -29,3 +29,5 @@ Each model annotates one cluster from its top 20 marker genes with a Cell Ontolo
Errors in the models' first answers (all models): label mismatch 59/276, marker not in data 1/276, no markers 0/276, not a cell type 0/276, obsolete id 1/276, unapproved symbol 0/276, unknown id 2/276.
276 episodes, 344 model calls (0 failed), 63 revised after feedback. Rule codes raised across all records: BEV004 21, BEV016 4, BEV017 65, BEV023 1.
+
+Funnel. First answers: conflict, to a person 15, identifier error 62, marker not in the data 1, passed 198. Answers with a fixable finding, after feedback: admitted 57, to a person 6. Final: admitted 255, to a person 21. Admitted, against the authors' term: compatible 205, disagrees 50. Expert audit of admitted records: not yet run.
diff --git a/tests/test_reproduce.py b/tests/test_reproduce.py
new file mode 100644
index 0000000..88fa14a
--- /dev/null
+++ b/tests/test_reproduce.py
@@ -0,0 +1,50 @@
+"""tools/reproduce.py covers every committed result and figure (running it is a CI job of its own)."""
+import importlib.util
+import sys
+from pathlib import Path
+
+import pytest
+
+ROOT = Path(__file__).resolve().parents[1]
+spec = importlib.util.spec_from_file_location("reproduce", ROOT / "tools" / "reproduce.py")
+reproduce = importlib.util.module_from_spec(spec)
+sys.modules["reproduce"] = reproduce # dataclasses look their module up while the class is built
+spec.loader.exec_module(reproduce)
+
+
+def covered() -> set[Path]:
+ return {committed for step in reproduce.STEPS for committed in step.outputs}
+
+
+def test_every_committed_result_is_regenerated():
+ results = [p for d in [*ROOT.glob("examples/*/results"), *(ROOT / "evaluation/llm_benchmark/results").iterdir()]
+ for p in d.iterdir() if p.is_file()]
+ inputs = {p for step in reproduce.STEPS for p in step.inputs} # replayed from, not regenerated
+ missing = [str(p.relative_to(ROOT)) for p in results if p not in covered() and p not in inputs]
+ assert results and not missing, missing
+
+
+def test_every_figure_is_regenerated():
+ figures = sorted((ROOT / "docs" / "assets").glob("*.svg"))
+ assert figures and all(f in covered() for f in figures), [f.name for f in figures if f not in covered()]
+
+
+def test_list_and_unknown_steps(capsys):
+ assert reproduce.main(["--list"]) == 0
+ listed = capsys.readouterr().out
+ assert all(step.name in listed for step in reproduce.STEPS)
+ with pytest.raises(SystemExit):
+ reproduce.main(["--only", "no-such-step"])
+
+
+def test_text_comparison_ignores_line_endings_only(tmp_path):
+ a, b, c = tmp_path / "a.svg", tmp_path / "b.svg", tmp_path / "c.svg"
+ a.write_bytes(b"\n")
+ b.write_bytes(b"\r\n")
+ c.write_bytes(b"\n")
+ assert reproduce.same(a, b) and not reproduce.same(a, c)
+
+
+def test_a_check_only_step_runs(capsys):
+ assert reproduce.main(["--only", "error-taxonomy"]) == 0
+ assert "identical error-taxonomy" in capsys.readouterr().out
diff --git a/tools/reproduce.py b/tools/reproduce.py
new file mode 100644
index 0000000..d6ecd33
--- /dev/null
+++ b/tools/reproduce.py
@@ -0,0 +1,172 @@
+"""Regenerate every committed benchmark result and figure, offline, and compare them with the repository.
+
+ uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py # check; exit 1 on any difference
+ uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py --write # update the committed files
+ uv run --frozen --with matplotlib==3.11.2 python tools/reproduce.py --only celltype-test figures
+ uv run --frozen python tools/reproduce.py --list
+
+Model calls, agent runs and downloads are not repeated. What they produced is committed: model answers, agent
+episodes, the verification of cited papers, and content-addressed source snapshots. Every table, summary and figure is
+recomputed from them. Each step runs in a scratch directory and its outputs are compared with the committed files:
+text with line endings normalised (the repository stores LF), everything else byte for byte. The figures are
+byte-stable for one matplotlib version, so the command pins it.
+"""
+from __future__ import annotations
+
+import argparse
+import shutil
+import subprocess
+import sys
+import tempfile
+import time
+from dataclasses import dataclass, field
+from pathlib import Path
+
+REPO = Path(__file__).resolve().parents[1]
+BENCH = REPO / "evaluation" / "llm_benchmark"
+RESULTS = BENCH / "results"
+ASSETS = REPO / "docs" / "assets"
+MATPLOTLIB = "3.11.2"
+TEXT = {".json", ".jsonl", ".md", ".csv", ".svg", ".txt", ".tsv"}
+
+
+@dataclass
+class Step:
+ name: str
+ what: str
+ commands: list[list[str]] # run in order; "{out}" is replaced by the scratch directory
+ inputs: list[Path] = field(default_factory=list) # committed files the step replays from, copied into scratch
+ outputs: dict[Path, str] = field(default_factory=dict) # committed file -> name in scratch
+ check_only: bool = False # a self-checking command (exit status only)
+ write_commands: list[list[str]] | None = None
+ figures: bool = False
+
+
+def folder(path: Path, skip: tuple[str, ...] = ()) -> dict[Path, str]:
+ return {p: p.name for p in sorted(path.iterdir()) if p.is_file() and p.name not in skip}
+
+
+def py(script: Path, *args: str) -> list[str]:
+ return [sys.executable, str(script), *args]
+
+
+def replay(name: str, what: str, script: str, args: list[str], inputs: list[str], outputs: list[str]) -> Step:
+ base = RESULTS / name
+ return Step(name, what, [py(BENCH / script, *args)], [base / i for i in inputs], {base / o: o for o in outputs})
+
+
+def case(name: str, what: str) -> Step:
+ """A real-data case: run.py writes a fresh directory (it refuses to overwrite earlier evidence)."""
+ results = REPO / "examples" / name / "results"
+ return Step(name.replace("_", "-"), what, [py(REPO / "examples" / name / "run.py", "--output", "{out}/run")],
+ outputs={p: f"run/{n}" for p, n in folder(results).items()})
+
+
+STEPS = [
+ Step("error-taxonomy", "Error taxonomy page from evaluation/error_taxonomy.yaml and the case results",
+ [py(REPO / "tools" / "render_taxonomy.py", "--check")], check_only=True,
+ write_commands=[py(REPO / "tools" / "render_taxonomy.py")]),
+ Step("llm-tasks", "LLM benchmark task files from the pinned ClinVar and CIViC sources",
+ [py(BENCH / "tasks.py", "--check")], check_only=True),
+ Step("literature-tasks", "Literature task files", [py(BENCH / "tasks_literature.py", "--check")], check_only=True),
+ Step("semantic-units", "Semantic-check units",
+ [py(BENCH / "semantic_eval.py", "units", "--split", "pilot", "--check")], check_only=True),
+ case("vbo_canine", "VBO canine name mapping: decisions, controlled faults, trust boundary"),
+ case("clinvar_germline", "ClinVar germline: policy reproduction, stability 2023 to 2026, faults"),
+ case("civic_literature", "CIViC literature grounding: negative controls on pinned papers"),
+ replay("pilot", "LLM benchmark, ClinVar tasks", "score.py", ["--split", "pilot", "--output", "{out}"],
+ ["answers.jsonl"], ["rows.jsonl", "summary.json", "summary.md"]),
+ replay("literature-pilot", "LLM benchmark, literature tasks with the source", "score_literature.py",
+ ["--split", "pilot", "--output", "{out}"], ["answers.jsonl"], ["rows.jsonl", "summary.json", "summary.md"]),
+ replay("literature-plain-pilot", "Scenario 1a: plain questions with PMID and title", "score_literature.py",
+ ["--split", "pilot", "--output", "{out}"], ["answers.jsonl"], ["rows.jsonl", "summary.json", "summary.md"]),
+ replay("literature-claims-pilot", "Scenario 1b: plain questions, the model picks the papers", "score_claims.py",
+ ["score", "--output", "{out}"], ["answers.jsonl", "verification.jsonl"],
+ ["rows.jsonl", "summary.json", "summary.md"]),
+ replay("semantic-pilot", "Semantic checks: independent review and cues", "semantic_eval.py",
+ ["score", "--split", "pilot", "--output", "{out}"], ["answers.jsonl"],
+ ["rows.jsonl", "summary.json", "summary.md"]),
+ replay("agent-pilot", "Scenario 2: agent with PubMed tools and feedback", "agent_loop.py",
+ ["score", "--results", "{out}"], ["episodes.jsonl"], ["summary.json", "summary.md"]),
+ replay("agent-stance-pilot", "Scenario 2b: stances and a conflicting outcome", "agent_loop.py",
+ ["score", "--results", "{out}"], ["episodes.jsonl"], ["summary.json", "summary.md"]),
+ replay("celltype-pilot", "Scenario 3: single-cell annotation, pilot (protocol 1)", "celltype_loop.py",
+ ["score", "--results", "{out}"], ["episodes.jsonl"], ["summary.json", "summary.md"]),
+ replay("celltype-test", "Scenario 3: single-cell annotation, held-out (protocol 2)", "celltype_loop.py",
+ ["score", "--results", "{out}"], ["episodes.jsonl"], ["summary.json", "summary.md"]),
+ replay("celltype-external", "Scenario 3: single-cell annotation, external studies (protocol 3)", "celltype_loop.py",
+ ["score", "--results", "{out}"], ["episodes.jsonl"], ["summary.json", "summary.md"]),
+ Step("figures", "Figures in docs/assets, from the committed summaries",
+ [py(REPO / "examples" / "clinvar_germline" / "plot.py", "--output", "{out}/clinvar_germline_benchmark.svg"),
+ py(REPO / "examples" / "vbo_canine" / "plot.py", "--output", "{out}/vbo_canine_benchmark.svg"),
+ py(BENCH / "plot.py", "--output", "{out}/ai_validation_results.svg", "--funnel", "{out}/ai_validation_funnel.svg")],
+ outputs={ASSETS / n: n for n in ("clinvar_germline_benchmark.svg", "vbo_canine_benchmark.svg",
+ "ai_validation_results.svg", "ai_validation_funnel.svg")}, figures=True),
+]
+
+
+def same(committed: Path, produced: Path) -> bool:
+ a, b = committed.read_bytes(), produced.read_bytes()
+ if committed.suffix in TEXT:
+ a, b = a.replace(b"\r\n", b"\n"), b.replace(b"\r\n", b"\n")
+ return a == b
+
+
+def run(step: Step, write: bool) -> tuple[str, str]:
+ """(status, detail) for one step."""
+ if step.figures:
+ try:
+ import matplotlib
+ except ImportError:
+ return "skipped", f"needs matplotlib=={MATPLOTLIB} (uv run --with matplotlib=={MATPLOTLIB})"
+ if matplotlib.__version__ != MATPLOTLIB:
+ return "skipped", f"needs matplotlib=={MATPLOTLIB}, found {matplotlib.__version__}"
+ with tempfile.TemporaryDirectory(prefix=f"reproduce-{step.name}-") as scratch:
+ out = Path(scratch)
+ for source in step.inputs:
+ shutil.copyfile(source, out / source.name)
+ for command in (step.write_commands if write and step.write_commands else step.commands):
+ done = subprocess.run([part.replace("{out}", scratch) for part in command], cwd=out, capture_output=True,
+ text=True, encoding="utf-8", errors="replace")
+ if done.returncode != 0:
+ message = (done.stderr or done.stdout).strip().splitlines()
+ return "failed", message[-1] if message else f"exit {done.returncode}"
+ if step.check_only:
+ return ("written" if write and step.write_commands else "identical"), ""
+ different = [c for c, name in step.outputs.items() if not (out / name).exists() or not same(c, out / name)]
+ if write:
+ for committed, name in step.outputs.items():
+ if (out / name).exists() and not same(committed, out / name):
+ committed.write_bytes((out / name).read_bytes().replace(b"\r\n", b"\n")
+ if committed.suffix in TEXT else (out / name).read_bytes())
+ return ("written" if different else "identical"), ", ".join(c.name for c in different)
+ if different:
+ return "different", ", ".join(str(c.relative_to(REPO)) for c in different)
+ return "identical", f"{len(step.outputs)} file(s)"
+
+
+def main(argv: list[str] | None = None) -> int:
+ parser = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
+ parser.add_argument("--write", action="store_true", help="update the committed files with what is regenerated")
+ parser.add_argument("--only", nargs="+", metavar="STEP", help="run only these steps")
+ parser.add_argument("--list", action="store_true", help="list the steps and exit")
+ args = parser.parse_args(argv)
+ if args.list:
+ for step in STEPS:
+ print(f"{step.name:24} {step.what}")
+ return 0
+ unknown = set(args.only or []) - {s.name for s in STEPS}
+ if unknown:
+ parser.error(f"unknown step(s): {', '.join(sorted(unknown))}")
+ failures = 0
+ for step in (s for s in STEPS if not args.only or s.name in args.only):
+ started = time.monotonic()
+ status, detail = run(step, args.write)
+ failures += status in ("failed", "different", "skipped")
+ print(f"{status:10} {step.name:24} {time.monotonic() - started:6.1f}s {detail}", flush=True)
+ print("all reproduced" if not failures else f"{failures} step(s) not reproduced")
+ return 1 if failures else 0
+
+
+if __name__ == "__main__":
+ raise SystemExit(main())